Industry·
Suno Expands Beyond Music with Unified Voice‑and‑Music Generation
AI music platform Suno launches a public beta Speech feature that creates spoken narration and background music in a single track, targeting creators who need cohesive audio for podcasts, videos, and interactive experiences.
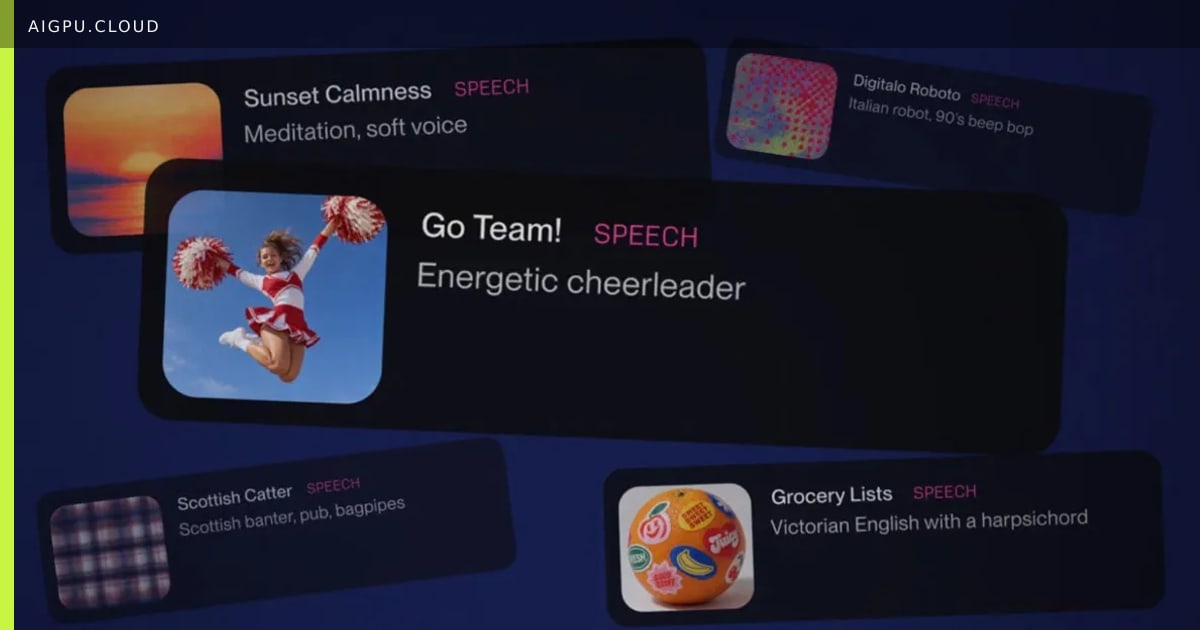
Suno, known for its generative music models, has introduced Speech — a beta capability that synthesizes voiceovers and optionally layers them with AI‑composed music. Users can choose a simple prompt mode or an advanced script mode, adjust voice gender, style, and variability, and generate clips up to eight minutes long.
Why it matters for GPU and AI infrastructure
Unified voice‑and‑music generation doubles the inference workload compared with standalone text‑to‑speech or music models, demanding higher GPU memory bandwidth and sustained compute for real‑time streaming. Cloud providers that offer scalable AI GPU clusters — such as AiGpu — can accelerate model iteration, reduce latency for interactive applications, and support the growing demand for multimodal audio pipelines.
The feature is still early; Suno acknowledges occasional accent drift and exaggerated pauses. Continuous user feedback will drive rapid model refinement, a cycle that benefits from elastic GPU resources for frequent retraining and A/B testing.
For enterprises building voice‑enabled products — from e‑learning narration to dynamic game dialogue — the ability to produce matched music beds in one call simplifies workflows and cuts licensing costs, making integrated AI audio a strategic differentiator.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- suno
- speech synthesis
- generative audio
- voice ai
By AiGpu Editorial · Editorial rewrite based on public reporting (The Verge AI)
← All articles