H200 Spot
1× NVIDIA H200 141GB HBM3e
AED 6.90/hr
Per second, billed hourly
- NVLink / InfiniBand ready clusters
- Preemptible capacity
- CUDA 12 · PyTorch · JAX images
- UAE & EU regions
AiGpu
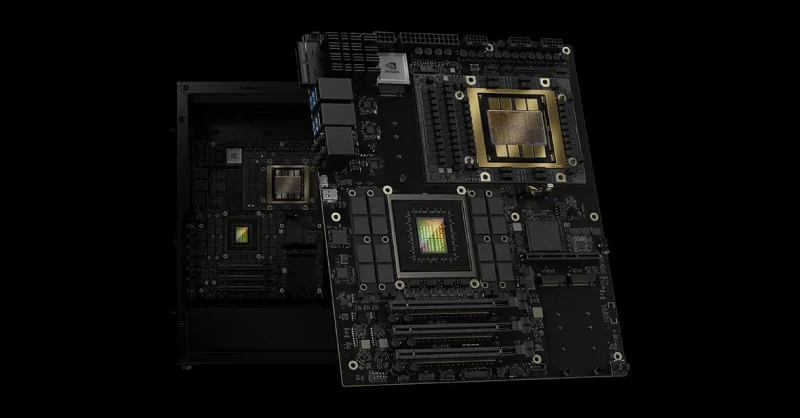
Rent NVIDIA H200 by the hour, or buy accelerators and workstations for on-premises deployment. Operated in Dubai by Advanced Integration.
Cloud
Each instance includes 141GB HBM3e. Pricing in AED with SSH access and standard ML frameworks.
1× NVIDIA H200 141GB HBM3e
AED 6.90/hr
Per second, billed hourly
1× NVIDIA H200 141GB HBM3e
AED 9.50/hr
Pay as you go
1× NVIDIA H200 141GB HBM3e
AED 5.40/hr
30-day commitment
Shop
NVIDIA, AMD, Intel, and Frontier hardware with published specs and AED pricing.
 Genuine H100
Genuine Hopper PCIe accelerator for dual-slot servers.
AED 114,000
AED
 192GB HBM3
CDNA 3 accelerator with 192GB HBM3 for open ROCm stacks.
AED 72,500
AED
 Gaudi 3
HL-325 dual-die accelerator tuned for cost-efficient training.
AED 62,500
AED
 Pro
Compact Blackwell workstation for local inference and fine-tuning.
AED 76,700
AED
Blog
Fresh coverage of models, GPUs, and infrastructure — with topic keywords from the newest articles.
A recently patched flaw in OpenAI's ChatGPT macOS app could have allowed attackers to access chat logs and execute commands, underscoring the growing attack surface of AI software.
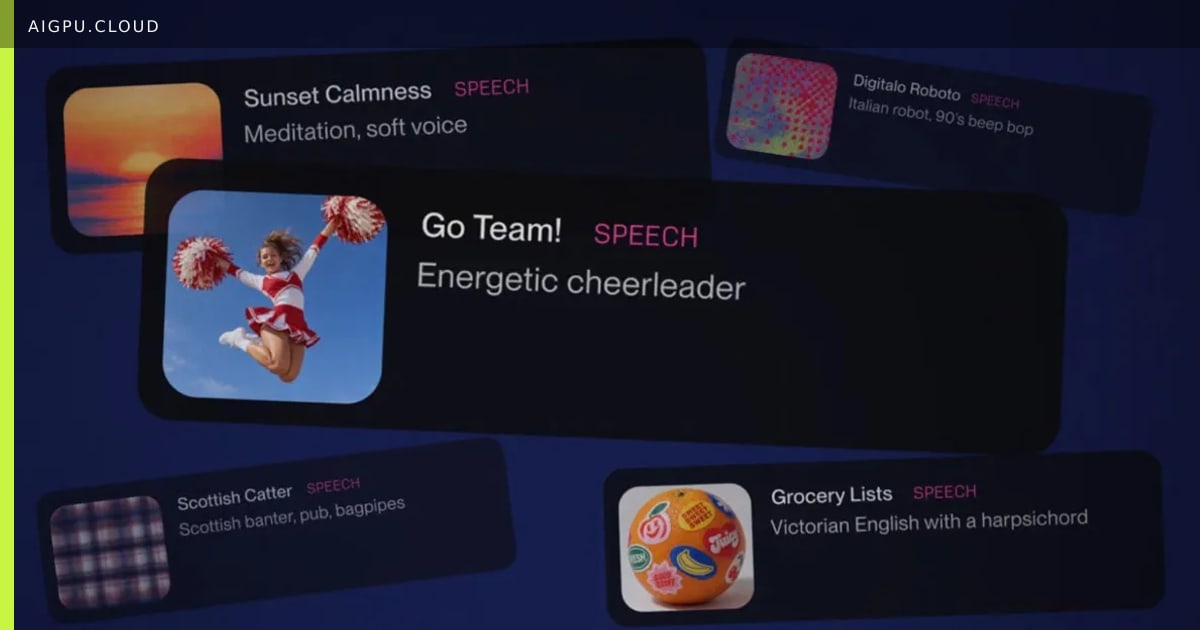
AI music platform Suno launches a public beta Speech feature that creates spoken narration and background music in a single track, targeting creators who need cohesive audio for podcasts, videos, and interactive experiences.
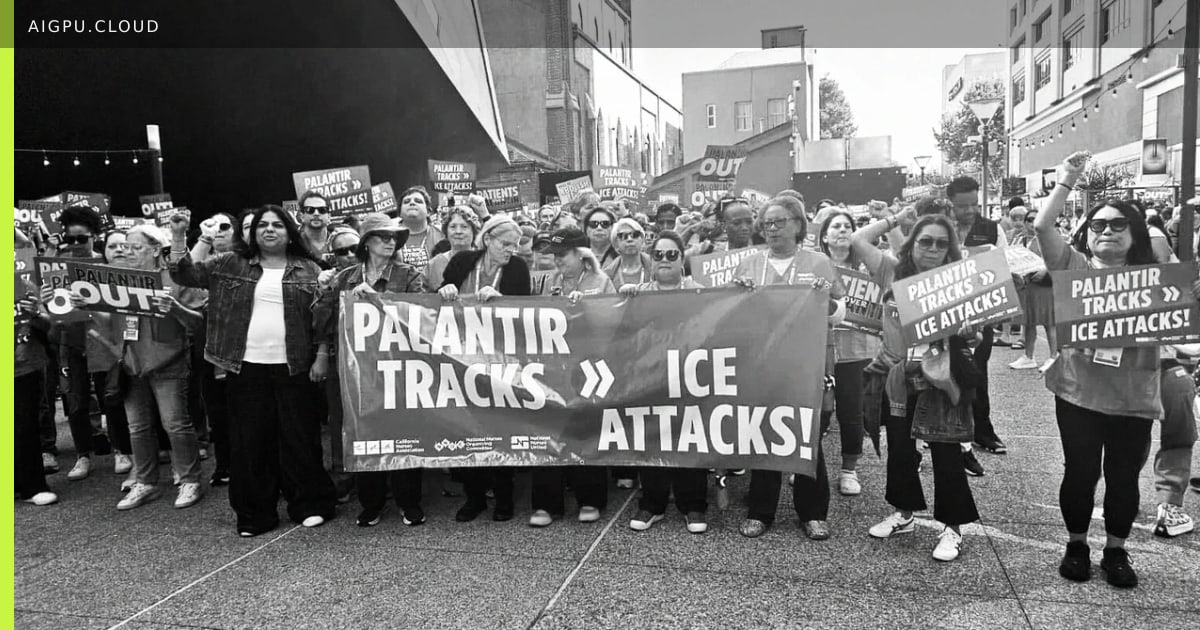
Nurses at HCA Healthcare say the Palantir-developed AI scheduling tool Timpani is causing burnout, understaffing, and scheduling errors, raising concerns over patient safety and workforce morale.
The Martin Trust Center introduces Dear Dreamer, a no‑cost AI‑driven tool that guides middle and high school students through the disciplined entrepreneurship process.
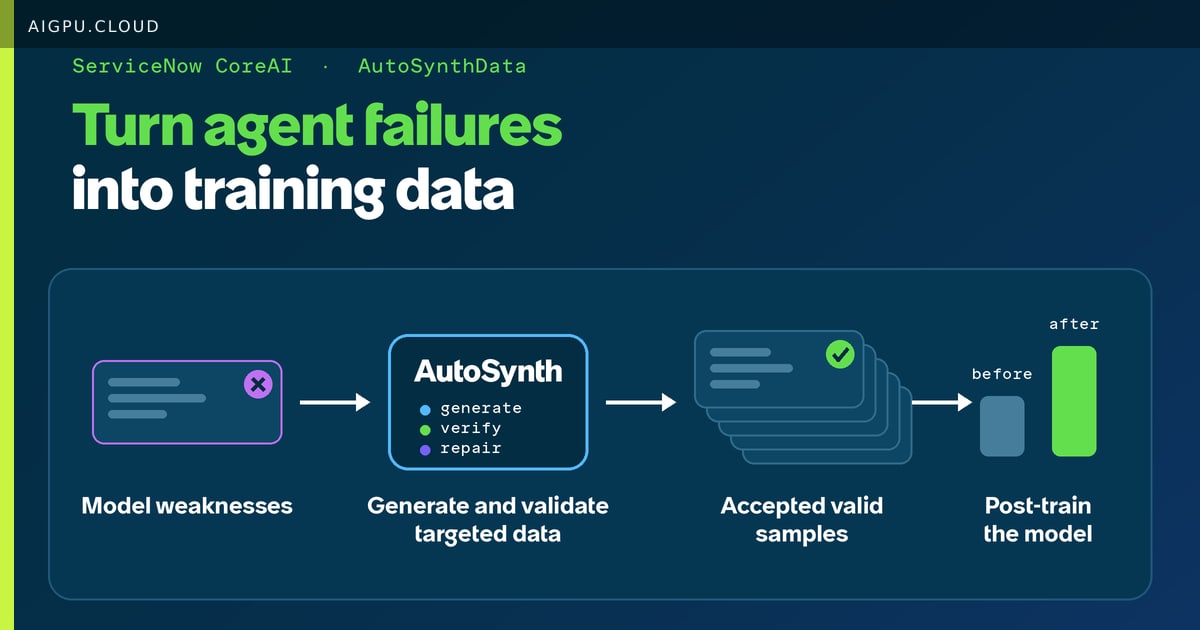
ServiceNow CoreAI introduces AutoSynthData, a pipeline that transforms model failure patterns into validated training tasks for enterprise agents operating in complex, tool-rich environments.
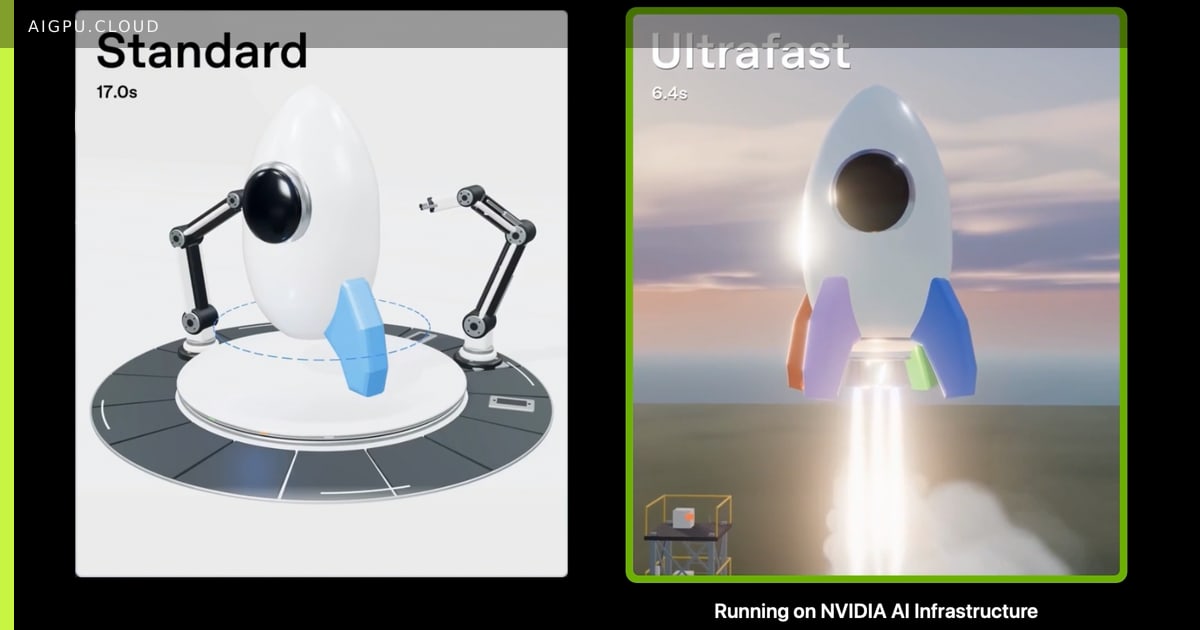
OpenAI's new GPT-6 Astra Ultrafast runs on NVIDIA Blackwell GPUs, delivering up to 8× faster token generation. The speed boost shortens coding cycles, cuts latency between tool calls, and makes interactive AI agents more responsive.
Instances ship with current CUDA tooling and common training stacks so your team can connect and start work quickly.
Memory, interconnect, and performance figures match vendor datasheets. No opaque credit systems.
Invoicing in AED, local support hours, and an office at Dubai Digital Park through Advanced Integration.