Hardware·
NVIDIA Unveils Local AI Hardware Stack at GTC Berlin: RTX Spark, DGX Spark, and DGX Station
At GTC Berlin, NVIDIA introduced a three-tier local AI hardware portfolio — RTX Spark for personal agents on Windows, DGX Spark for developers on Linux, and DGX Station for enterprise workloads — alongside new 64GB configurations, clustering software, and day-zero model support.
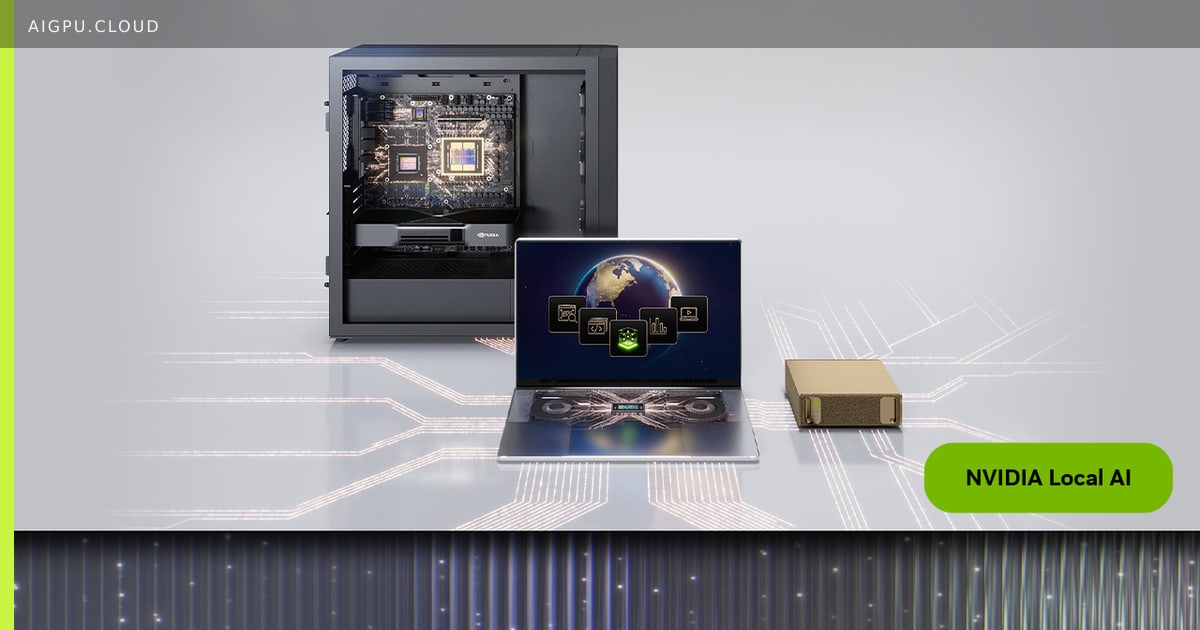
NVIDIA used GTC Berlin to lay out a complete on-premise AI compute ladder. At the entry level, RTX Spark laptops deliver up to 128 GB of unified memory and 1 petaflop of AI compute, enabling personal agents, accelerated content creation, and 1440p 100 FPS gaming on Windows. The new Underdog Desktop Agent runs models entirely on-device via its Husky inference engine, keeping user data local. Reviewers from CGMag, The Verge, and PCMag have praised the platform's capability and portability since its October 16 launch.
Developer and Enterprise Tiers
DGX Spark 64 GB systems begin shipping October 23, targeting developers who need to run models such as Nemotron 3.5 Bolt 74B, Qwen 3.8 27B, and Gemma 4 26B-A4B on Linux. Built-in ConnectX-7 networking and the new NVIDIA Sync cluster manager let teams link up to eight DGX Spark units, while a Model Launcher and Wi-Fi Assistant arrive in the October software update. For larger teams, DGX Station adds seven manageability integrations, NVIDIA Cloud Functions early access, three open-source robotics reference workflows, and a Windows version slated for December with manufacturing-focused agent harnesses.
Across all tiers, NVIDIA announced day-zero support for the latest Nemotron, GLM, DeepSeek, Qwen, MiniMax, and FLUX.3 models, plus optimized checkpoints and fresh accelerations for llama.cpp and vLLM inference engines. The Recursive Flint coding model is also available immediately on local NVIDIA hardware.
Why It Matters for GPU / AI Infrastructure
For organizations building sovereign or latency-sensitive AI pipelines, this stack removes the cloud dependency for experimentation and inference. The unified memory architecture on RTX Spark and DGX Spark simplifies model deployment, while Sync clustering turns workstation-class boxes into a coherent compute fabric — a practical step toward on-premise AI factories without data-center-scale investment.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- nvidia
- local ai
- dgx spark
- rtx spark
By AiGpu Editorial · Editorial rewrite based on public reporting (NVIDIA Blog)
← All articles