Industry·
NVIDIA and AI4Bharat Launch 2.8 Trillion-Token Indic Language Dataset with Open GPU Pipeline
A joint initiative between NVIDIA and India's AI4Bharat lab delivers a massive open dataset for 22 Indian languages, powered by a GPU-accelerated data generation pipeline for synthetic text creation.
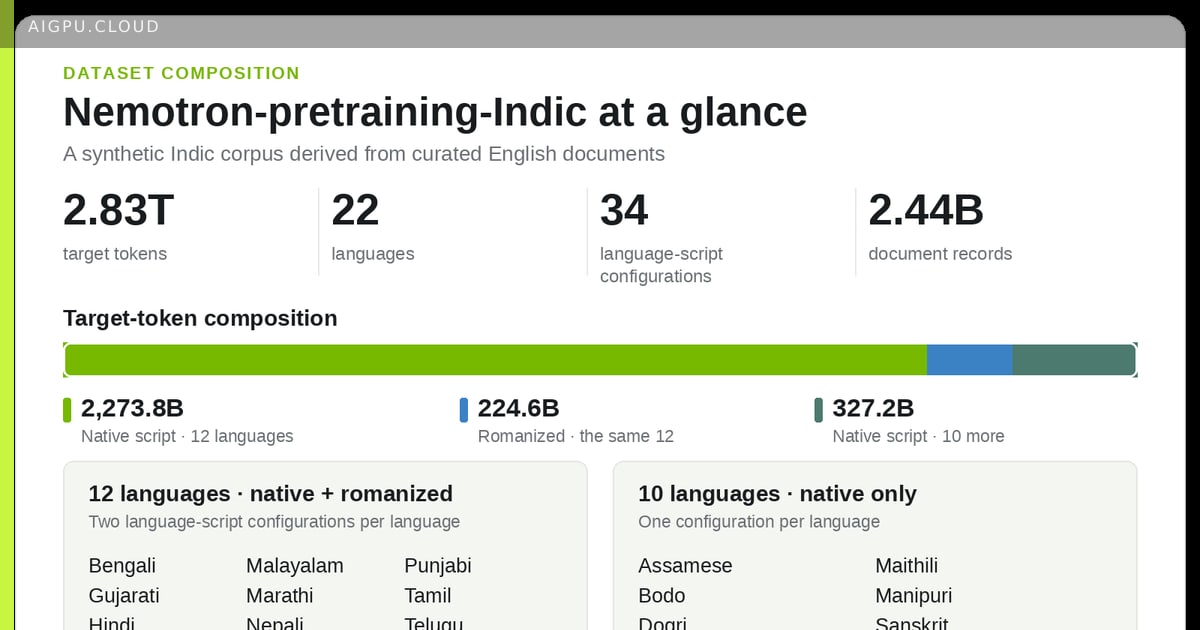
NVIDIA and AI4Bharat have unveiled a groundbreaking initiative to advance Indic language AI development through a massive-scale dataset and open-source infrastructure. The collaboration produces Nemotron-pretraining-Indic-v1, a corpus encompassing approximately 2.8 trillion tokens across 22 Indian languages recognized in the nation's Constitution, covering 97% of the population.
The dataset combines native-script content for all 22 languages and romanized text for twelve, supporting 34 language-script configurations. Built using a GPU-accelerated pipeline, the data generation process includes document-level translation, quality assessment, and targeted repair workflows, ensuring synthetic text remains grounded in curated source material while preserving technical elements like equations and code.
Key features of the pipeline include full reproducibility, with prompts, LLM workflows, and quality checks shared openly. Developers can adapt the framework to their own source documents or leverage the corpus directly for training models capable of explaining technical concepts and solving problems in Indian languages.
Why it matters for GPU / AI infrastructure: This release underscores the critical role of scalable GPU resources in synthetic data generation for underrepresented languages. The open pipeline enables cloud providers to replicate and extend the workflow, reducing barriers to building high-quality Indic language models while maximizing GPU utilization for translation and quality assurance tasks.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- indic languages
- gpu pipeline
- nvidia
- ai training data
By AiGpu Editorial · Editorial rewrite based on public reporting (Hugging Face Blog)
← All articles