Industry·
LiquidAI Releases Open d1 Decision Models Optimized for Edge Deployment
LiquidAI unveils d1-3B and d1-omni-600M, multimodal decision models that deliver sub-50ms inference on NVIDIA Jetson hardware, setting new benchmarks for edge AI decision-making.
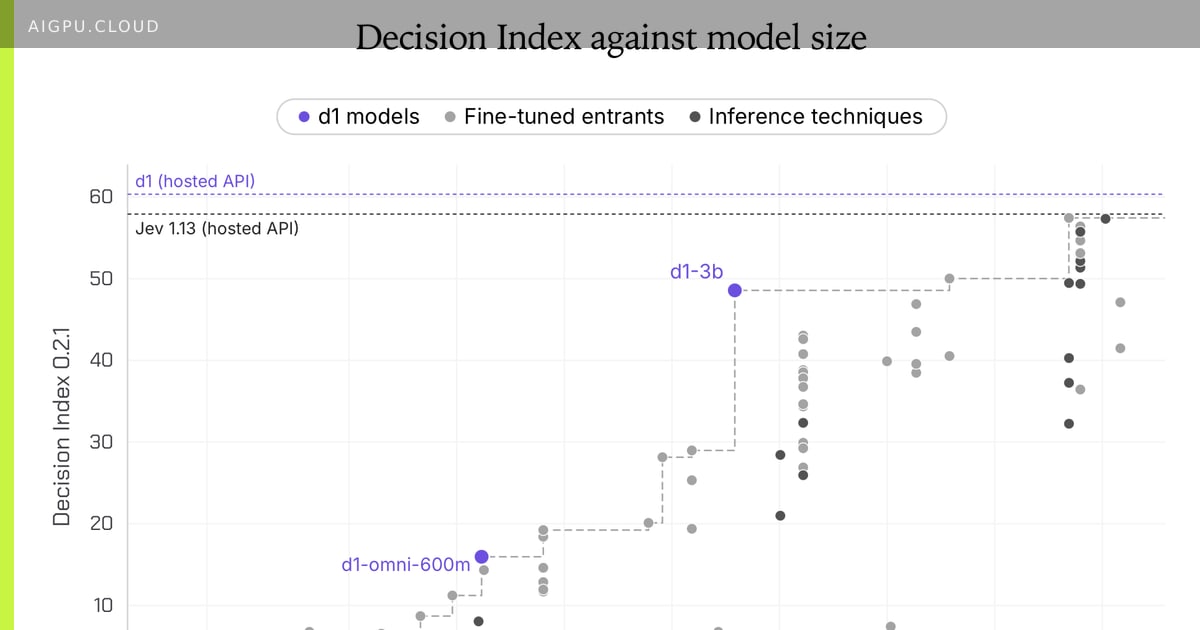
LiquidAI has open-sourced two decision models in its new d1 family: the 3-billion-parameter d1-3B and the experimental 600-million-parameter d1-omni-600M. Unlike generative LLMs that emit tokens sequentially, these models produce a decision in a single forward pass, making them purpose-built for latency-critical edge workloads such as robotics, industrial inspection, and real-time content moderation.
On the Decision Index 0.2.1, d1-3B scores 48.57, outperforming every 4B and 9B baseline and even the 35B-parameter Decider 35B-A3B (47.11). Across seven public benchmarks covering reading comprehension, toxicity detection, intent classification, medical QA, and cross-lingual understanding, d1-3B averages 82.9 while the tiny d1-omni-600M averages 78.4 — surpassing Decider 2B with only a quarter of the parameters.
Multimodal from the ground up
d1-3B inherits vision-language capability from the LFM2.5-VL-3B decoder backbone, accepting text and images. The experimental d1-omni-600M builds on a bidirectional LFM2.5-Encoder-350M core and adds separate vision and audio encoders, enabling either text-image or text-audio input pairs. This architecture keeps the model footprint small while covering three modalities — a rare combination in the sub-1B class.
In collaboration with NVIDIA, LiquidAI measured d1-3B on the full Jetson stack. Single-question latency hits 16 ms on AGX Thor, 26 ms on AGX Orin 64 GB, and 50 ms on Orin Nano. Batching three questions adds only ~20 % overhead, and a 384-pixel image adds roughly 20 ms on Thor. On an RTX 4090, the same query resolves in 8 ms. These numbers demonstrate that high-quality decision inference no longer requires data-center GPUs.
Why it matters for GPU / AI infrastructure: Decision models that run in single-digit milliseconds on embedded Jetson modules change the economics of edge AI. Teams can now deploy deterministic, multimodal reasoning on existing NVIDIA edge fleets without provisioning cloud fallback, reducing bandwidth, latency, and operational cost for real-time automation.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- edge ai
- decision models
- liquidai
- nvidia jetson
By AiGpu Editorial · Editorial rewrite based on public reporting (Hugging Face Blog)
← All articles