Research·
XYBench: A New Benchmark for Detecting Misguided User Requests
Researchers from Allen Institute, Carnegie Mellon, NVIDIA, and Johns Hopkins release XYBench, an 8,000‑question benchmark that measures how well LLMs spot hidden misconceptions and steer users toward the real solution.
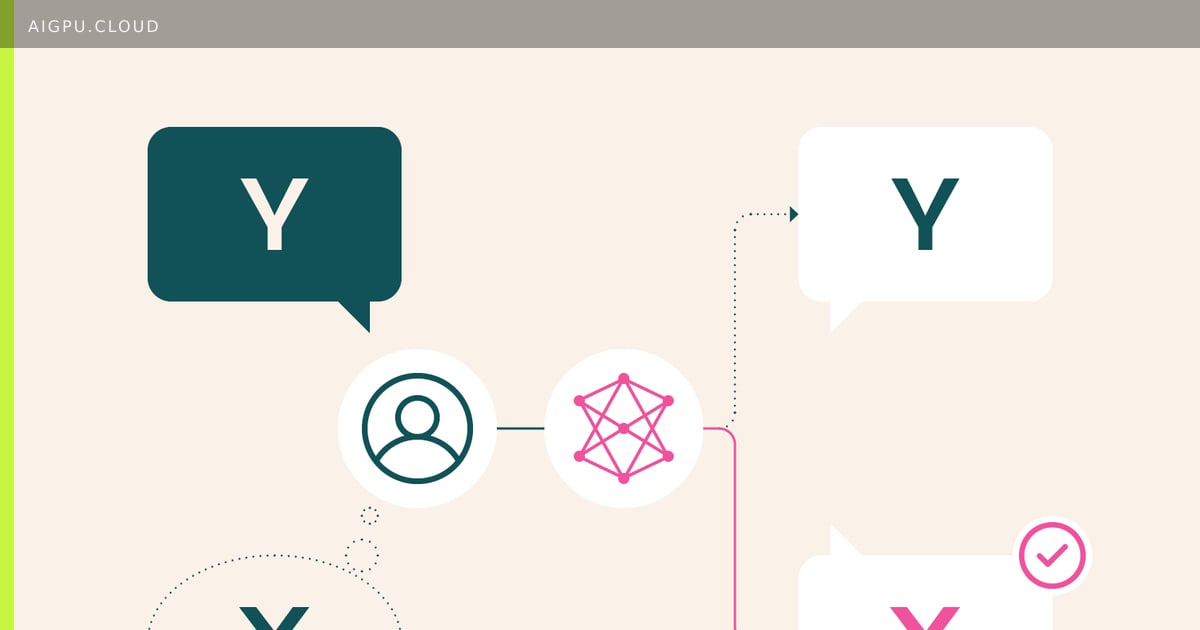
Large language models are increasingly used as everyday assistants, yet they often answer the literal question without checking whether the user’s premise is sound. XYBench addresses this gap by collecting 8,115 real‑world queries — ranging from programming bugs to cooking mishaps — where the asker’s stated approach (Y) hides a deeper goal (X).
How the benchmark was built
The dataset draws from Stack Overflow, Stack Exchange, hand‑crafted examples, and procedurally generated questions based on WikiHow guides. For each item the team identified the explicit request, the inferred true intent, and verified that a straight answer to the literal request would not solve the problem.
Evaluations on five frontier models — Claude Sonnet 4.6, GPT‑5, Gemini 3.1 Pro, Qwen3.5‑9B, and DeepSeek‑V4 Pro — show that all systems frequently propose a fix for the stated approach but rarely redirect the user to the more effective underlying solution, unlike human expert answers.
By quantifying this “XY problem” behavior, XYBench gives researchers a concrete metric for improving model reasoning, explanation, and safe redirection — capabilities that are essential for trustworthy AI assistants deployed at scale.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- benchmark
- llm evaluation
- xybench
- ai assistants
By AiGpu Editorial · Editorial rewrite based on public reporting (Hugging Face Blog)
← All articles