Industry·
Voice AI Still Hunting for Its Breakthrough Moment
Despite billions in funding and full-duplex models, voice AI lacks the transformative leap that ChatGPT delivered for text. Leaders from PolyAI and Otter explain why reasoning speed, transcription accuracy, and emotional nuance remain the critical gaps.
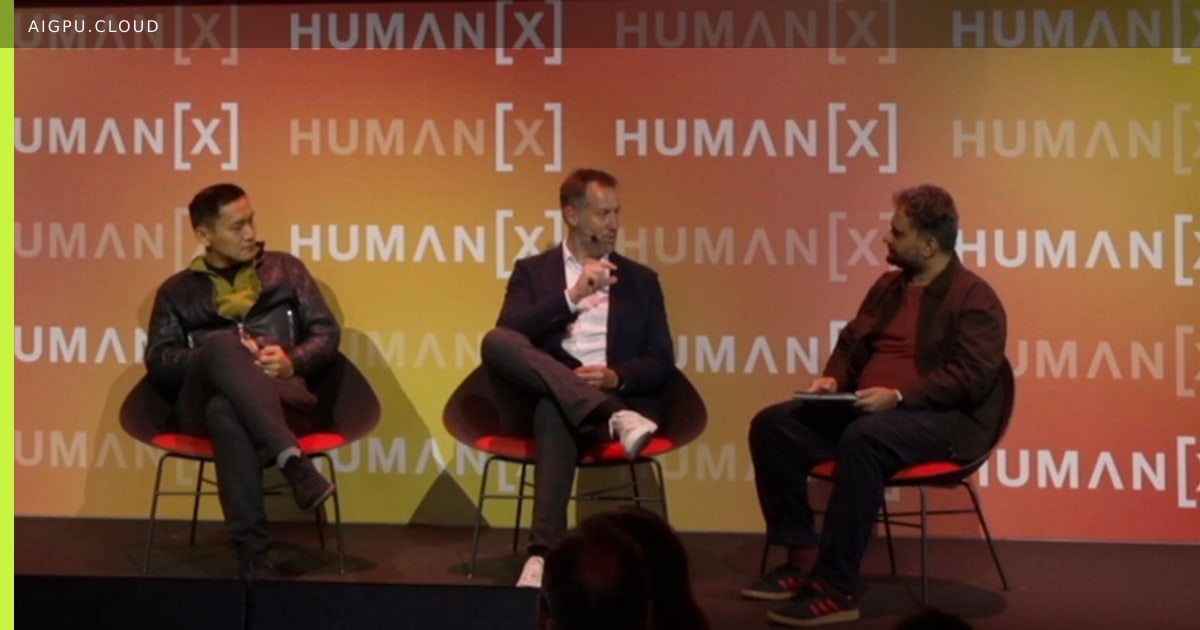
Investors have poured billions into voice AI startups spanning model builders, enterprise contact centers, meeting assistants, and dictation tools. New releases claim human-like conversation weekly, yet the sector has not experienced its "ChatGPT moment" — the inflection point where adoption accelerates from curiosity to necessity.
The Reasoning Latency Barrier
PolyAI CTO Shawn Wen notes that full-duplex architectures — capable of speaking while listening — are now a solved milestone. The next hurdle is reasoning speed: models must retrieve and formulate answers fast enough that dialogue feels natural, not stilted. In customer service, callers need confidence within the first two or three turns that the agent can actually resolve their issue, not just sound polite.
Otter CMO Alex Gay emphasizes that speaker identification, intent capture, and integration with organizational knowledge are prerequisites for true meeting automation. The company's digital twin initiative demands voices that convey the same emotive range as human participants — debate, strategy, relationship — otherwise the avatar remains a glorified Q&A bot.
Accuracy as a Trust Foundation
Both executives converge on automatic speech recognition (ASR) quality as the bedrock. Missed keywords fracture context; flawed transcripts cascade into faulty summaries and misguided actions, eroding user trust. Otter treats transcription not as an endpoint but as the layer upon which all downstream productivity gains depend. Continuous ASR improvement is non-negotiable.
Transparency is equally critical. Tools must disclose when recording or when an AI is speaking. Otter notifies all meeting participants even when its bot is absent, and PolyAI advocates clear signaling to callers. Trust, once lost, is difficult to rebuild in voice interfaces.
Why it matters for GPU / AI infrastructure: Real-time, low-latency voice reasoning at scale demands massive inference compute — optimized GPUs, high-bandwidth memory, and efficient model serving stacks. As full-duplex and emotive models proliferate, infrastructure providers that deliver consistent sub-100ms latency will capture the next wave of enterprise voice workloads.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- voice ai
- asr
- enterprise ai
- inference infrastructure
By AiGpu Editorial · Editorial rewrite based on public reporting (TechCrunch AI)
← All articles