Infrastructure·
Full-Stack Codesign: How NVIDIA Squeezes More AI Performance From Every Byte of Memory
NVIDIA's full-stack codesign approach — spanning GPUs, CPUs, networking, storage, and software — delivers up to 30× better agentic throughput per dollar despite only a 3% HBM capacity increase from Blackwell Ultra to Vera Rubin.
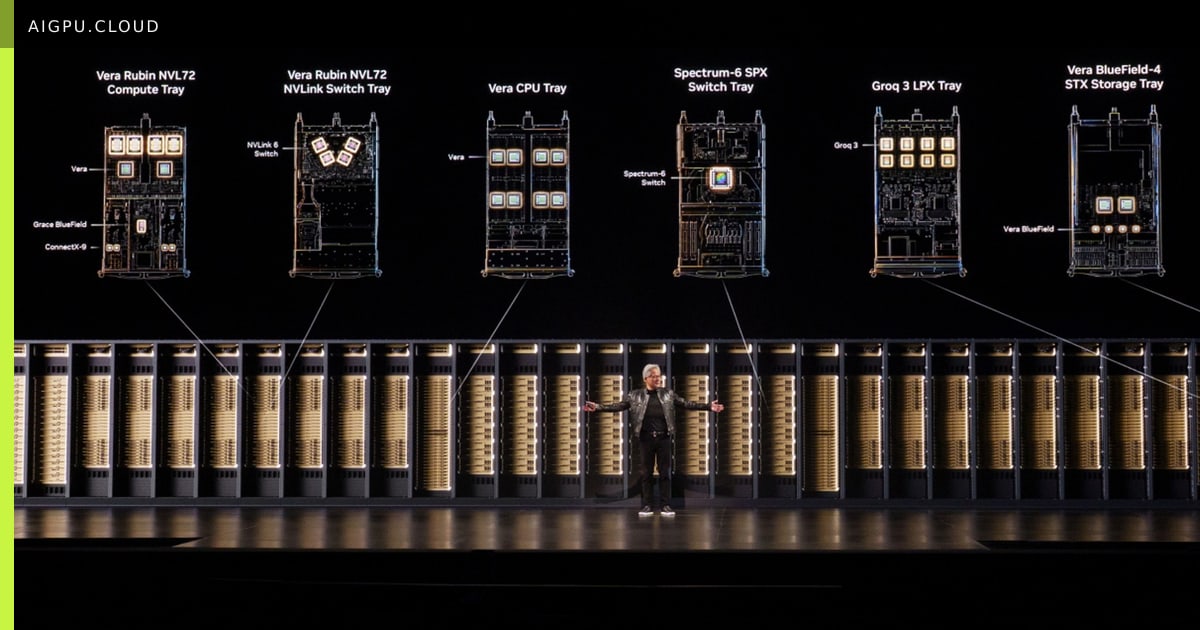
Larger models, longer contexts, and agentic workloads are pushing GPU memory to its limits. NVIDIA's response isn't simply stacking more HBM onto accelerators — it's a deliberate full-stack codesign strategy that optimizes how every byte moves across the entire memory hierarchy, from HBM through CPU memory, local SSDs, and shared storage.
Agentic inference compounds the pressure: trillion-parameter models, expanding KV caches, multi-million-token trajectories, and retrieval-augmented generation all compete for limited high-bandwidth memory. The memory wall — where bandwidth can't feed compute fast enough — means adding raw HBM capacity eventually yields diminishing returns.
Why it matters for GPU / AI infrastructure
From Blackwell Ultra to the Vera Rubin platform, NVIDIA increased HBM capacity per GPU by roughly 3%, yet agentic throughput per dollar jumped up to 30× on SemiAnalysis AgentX benchmarks. The gain comes from shrinking what must reside in HBM, placing data on the right tier, and prefetching before the GPU stalls — effectively making the memory hierarchy act as one cohesive system.
For AI factory operators, this means higher concurrent user density, lower cost per inference request, and better power efficiency without waiting for the next memory process node. The codesign philosophy extends across NVLink, NVLink Switch, Grace CPUs, BlueField DPUs, and the CUDA software stack, turning memory management into a competitive advantage rather than a bottleneck.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- memory hierarchy
- full-stack codesign
- agentic inference
- hbm optimization
By AiGpu Editorial · Editorial rewrite based on public reporting (NVIDIA Blog)
← All articles