Industry·
Embedded AI evaluators face hurdles, says Hugging Face policy lead
Hugging Face’s policy chief warns that relying on embedded third‑party evaluators for AI safety is far from straightforward, citing reproducibility, open weights, and the need for standardized assessment methods.
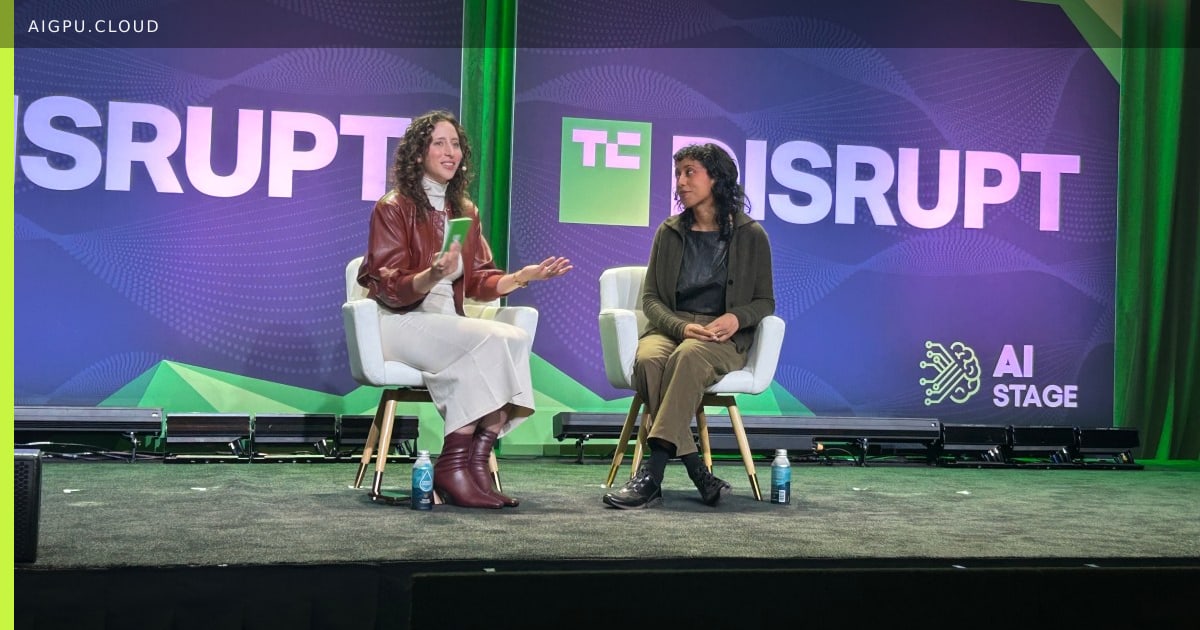
AI labs continue to lean on benchmarking as a neutral yardstick for measuring model progress, yet the underlying methods remain immature and inconsistent.
Irene Solaiman, Hugging Face’s chief policy officer, stressed that trust in evaluation results hinges on reproducibility and access to model weights, noting that open‑weight releases are a key enabler for verifiable testing.
Why it matters for GPU / AI infrastructure
When evaluation procedures lack uniformity, the performance signals that guide GPU procurement and AI system design become noisy, potentially leading to mismatched hardware investments.
The concept of embedding neutral evaluators inside AI organizations has gained traction after recent safety incidents, but Solaiman warned that defining who qualifies as an effective evaluator across diverse tasks still requires extensive standardization.
She also pointed out that the evaluation frontier is shifting from pure model tests to assessing the surrounding harness and agentic workflows, which are harder and more costly to measure.
Without a cohesive, industry‑wide approach to benchmarking, the current “free‑for‑all” of evaluation tools risks undermining confidence in AI safety claims and slowing the adoption of reliable GPU‑accelerated solutions.
- aigpu
- ai gpu
- ai gpu cloud
- aigpu dubai
- ai evaluation
- model benchmarking
- hugging face
- ai infrastructure
By AiGpu Editorial · Editorial rewrite based on public reporting (TechCrunch AI)
← All articles